Hire LLaMa Developer for Custom AI Solutions
Open-source power, enterprise-grade execution. Hire LLaMA developers from CodesClue to fine-tune, deploy, and scale Meta's LLaMA models into secure, production-ready AI applications built around your data and infrastructure.
Our developers bring deep expertise in Python, LoRA fine-tuning, quantization, RAG, and model deployment, turning open-source LLaMA into scalable applications tailored to your business logic. That could be a private AI assistant, a domain-specific chatbot, or an enterprise automation engine.
Consult Our Expert Llama Developers Now
Rated 4.9 on GoodFirms (opens in a new tab) and 5.0 on Clutch (opens in a new tab)Reply within one business day
- 8 Hours/day Full-Time AI Developers
- 4 Hours/day Part-Time AI Developers
- Pay as you go Hourly Hiring
Why Businesses Choose Llama Over Closed-Source APIs
Building with Llama gives businesses greater control over AI infrastructure, data, costs, and model customization. At CodesClue, our open source LLM developers help you move beyond API dependency by designing Llama-based solutions that fit your security, performance, and scalability requirements.
Hire LLaMA developersYou Own the Weights, Not Just the Access
Move beyond API dependency with Llama models you can deploy, customize, and govern within your own infrastructure. Hire an open source LLM developer from CodesClue to build self-hosted AI environments across your VPC, private cloud, or on-premises stack. Your model weights, prompts, outputs, and fine-tuning data stay under your control, with deeper security and customization.
Predictable Cost at Scale
Turn growing token consumption into an infrastructure strategy you can actually optimize. When you hire a Llama developer, our engineers benchmark inference workloads, evaluate GPU utilization, and select deployment architectures. They tune serving configurations to balance throughput, latency, and cost as usage scales.
Version-Specific Fine-Tuning
Don't overpay for model capacity you don't need. Hire a Llama 3 developer to match the right Llama variant and parameter size to your application's reasoning depth, context requirements, latency targets, and compute budget. From fine-tuning Llama 3.1 for complex enterprise workloads to optimizing smaller Llama 3.2 models for lightweight and edge use cases, we build around performance, not model size alone.
RAG-First Architecture with LlamaIndex
A powerful LLM cannot compensate for weak retrieval. Hire a LlamaIndex developer to engineer production-grade RAG pipelines with intelligent document chunking, metadata-aware retrieval, hybrid search, vector indexing, query transformation, and re-ranking. We connect Llama with your proprietary knowledge sources to deliver context-rich responses grounded in the information your business actually trusts.
Llama Model Fine-tuning Services We Offer
CodesClue provides specialized Llama model fine-tuning services to adapt open-weight models for domain-specific performance, efficient inference, and production-ready AI applications.
-
Domain-Specific Llama Fine-Tuning
Customize Llama with proprietary datasets using LoRA, QLoRA, and PEFT to improve task accuracy, terminology, response quality, and domain relevance without the overhead of full-model training.
-
Llama RAG & Knowledge Grounding
Connect Llama with your business knowledge using LlamaIndex, LangChain, vector databases, hybrid search, and re-ranking to build RAG systems that generate responses grounded in trusted enterprise data.
-
Llama 3 Model Customization
Hire a Llama 3 developer to select and customize the right Llama 3.x variant based on your context requirements, accuracy goals, latency expectations, model size, and available compute.
-
Llama Multimodal & Vision AI
Build vision-enabled Llama applications for document understanding, image analysis, visual question answering, and multimodal workflows, connecting text and visual intelligence within a unified AI solution.
-
Llama Chatbots & AI Copilots
Our LLM developers for hire build context-aware assistants by combining Llama with RAG, APIs, tool calling, and enterprise data. Create AI chatbots and copilots designed around your workflows and user needs.
-
Llama Inference & Quantization Optimization
Optimize Llama for production using GGUF, AWQ, GPTQ, vLLM, and TGI. Our engineers reduce memory requirements and improve inference speed, throughput, and GPU efficiency while aligning deployment with your infrastructure budget.
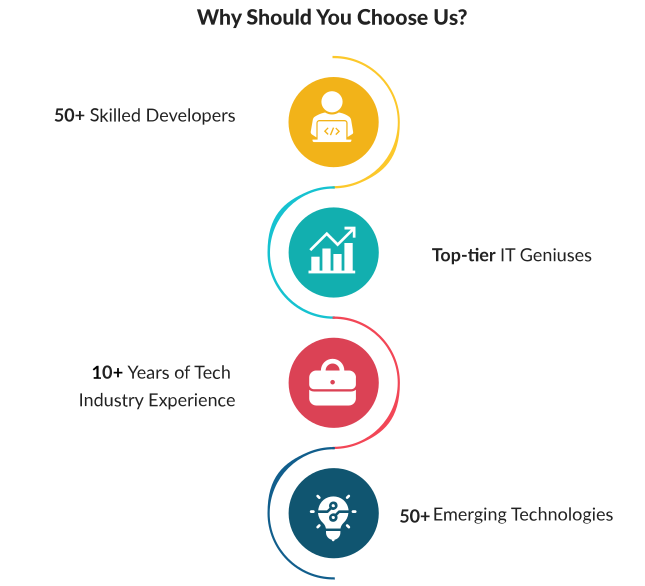
Why Businesses Choose CodesClue for AI Developers?
A Llama developer does more than connect an open-weight model to an application. They engineer the fine-tuning, quantization, inference serving, retrieval, and deployment layers that turn Llama into a reliable, production-ready AI system. At CodesClue, our specialists focus on the operational side of self-hosted LLMs, from adapting Llama 3.x models to optimizing inference and integrating enterprise knowledge.
Whether you need a Llama developer for a focused implementation or LLM developers for an end-to-end AI initiative, our team brings deep open-source LLM expertise to every stage of your project.
Key responsibilities
- Fine-Tune for Performance: Adapt Llama 3.x with LoRA/QLoRA for domain-specific behavior with minimal compute.
- Quantize for Efficiency: Use GGUF, AWQ, GPTQ to shrink memory needs for constrained GPU environments.
- Serve for Production: Deploy via vLLM and TGI with optimized batching for real-world throughput.
- Build RAG Pipelines: Engineer retrieval workflows with LlamaIndex and LangChain, tailored to your data.
- Handle Licensing: Address Llama Community License terms, usage thresholds, and attribution upfront.
Technical Stack We Cover
We work with modern, scalable, and industry-proven technologies across frontend, backend, mobile, cloud, and database systems. Our team selects the right stack based on your business requirements, performance expectations, and future scalability needs. From web and mobile frameworks to cloud infrastructure and DevOps tools, we build solutions that are secure, flexible, and growth ready.
- Back-End
- Node.js Ruby on Rails (RoR) Laravel Django Java Python PHP Express.js .Net Core NestJS
- AI & ML
- TensorFlow PyTorch Keras Scikit-learn OpenCV AWS AI Services IBM Watson Microsoft CNTK NLTK Evidently AI
- AI/ML Tools
- AI Agents Jupyter Anaconda PySpark Caffe2 GitHub Copilot ChatGPT
- AI & LLM Models
- GPT-4 GPT-3.5 GPT-3 LLaMA 3 LLaMA 2 DALL·E PaLM 2 Whisper Bard Midjourney Claude BERT
- Cloud
- AWS Microsoft Azure Google Cloud Platform Docker Kubernetes Terraform Jenkins Ansible
8 more categories we cover
- Front-End
- React.js Next.js Angular Vue.js Nuxt.js HTML CSS Bootstrap JavaScript TypeScript Tailwind CSS
- Database
- MongoDB MySQL PostgreSQL SQLite Firebase Redis
- Mobile Development
- Flutter iOS Android React Native
- UI/UX
- Figma Illustrator Photoshop Sketch
- Business Intelligence
- Tableau Power BI
- IoT
- AWS IoT Core Azure IoT Hub Raspberry Pi MQTT Arduino
- Automation
- UiPath Power Automate Automation Anywhere
- Testing & QA
- Selenium JUnit TestNG Cucumber Postman JMeter SonarQube TestRail Cypress
Why Enterprise Teams Trust CodesClue to Hire Llama Developers?
Deploying open-source LLMs at enterprise scale comes with real trade-offs around licensing, hardware costs, data control, and security, and getting any one of them wrong can be expensive.
CodesClue's Llama developers bring the operational discipline to get all four right from day one. They match model size and quantization to your actual infrastructure, keep your data within your own environment, and build compliance checks into the planning phase rather than discovering issues after deployment.
Hire Llama Developers Who Get the Trade-Offs Right
- Licensing checked against Meta's terms
- Hardware-matched model size and quantization
- Private deployment in your cloud or on-prem
- Flexible full-time or fixed-scope engagements
- Enterprise-grade security (NDA, ISO 27001, SOC 2)
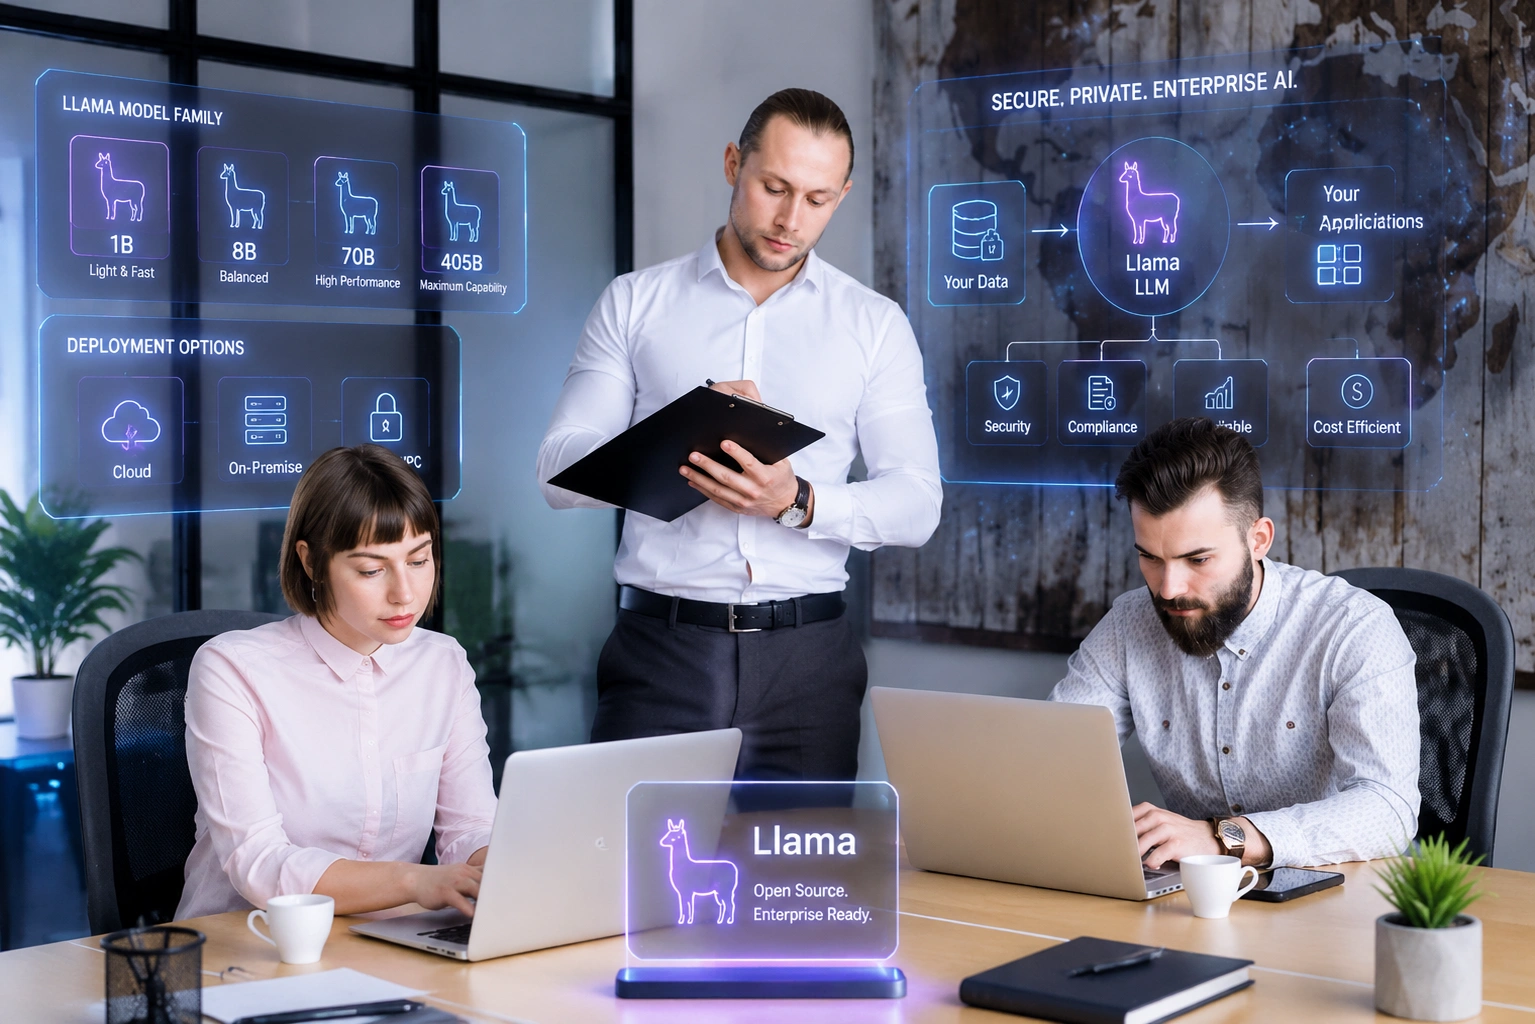
How to Hire a Llama Developer from CodesClue
Our simpler process makes it simple to hire a Llama developer with the right expertise, model knowledge, and infrastructure experience for your AI project.
-
Assess Your AI Requirements
We evaluate your data sensitivity, expected traffic, performance goals, and infrastructure needs to determine whether self-hosted Llama is the right choice for your use case.
-
Size Your Model & Infrastructure
Our experts recommend the right Llama version, model size, and quantization strategy based on your workload, GPU capacity, latency targets, and budget.
-
Fine-Tune & Integrate
We customize Llama using LoRA/QLoRA and integrate it with your application through LlamaIndex, RAG pipelines, APIs, and enterprise data sources.
-
Deploy, Optimize & Scale
Your Llama solution goes into production using vLLM or TGI, followed by continuous optimization for inference speed, GPU utilization, latency, and operating costs.
What our clients say
Startups, SMEs and large organizations trust us with their software projects. Here is what they say.
Send your requirements-
Was great to work with Ketan. Always optimistic, very professional and hard worker. Knew how to solve complex problems. Great project manager. Recommend them for web development.
 Nico Alexander, CEO at TracknTake
-
Communication was a key part of this any new features and updates were handled with care and done in a promptly manner. While what we were asking for was not always worded in the correct manner for the I.T. space they always understood what we were asking for.
Kasim, CEO at Snakz
-
A very client centric company with incredible top executives. They have years of experience and outstanding knowledge. Never faced an issue with scheduling meetings, or change notifications.
Mrulay, CEO at Therapix
-
CodesClue Technologies delivered a high-quality product that met the client's expectations. The team maintained high professionalism and clear communication throughout the engagement. Moreover, they were highly responsive to the client's needs and proactive in problem-solving.
Ibrahim al Sulati
-
CodesClue Technologies built a secure, user-friendly platform for managing digital legacies on NextLifeBook. The team ensured seamless functionality, strong data security, and an intuitive experience. Despite challenges, their dedication and attention to detail delivered a meaningful product that helps users plan and preserve their legacy effectively.
Lucas White
Frequently Asked Questions
Straight answers to what clients ask us before they hire.
Need a Custom Solution?
- NDA signed before we start
- Interview developers before you hire
- Daily progress updates
Is Llama actually free to use commercially?
Llama models are available for commercial use under Meta’s applicable Llama Community License, but they are not simply “free with no conditions.” Our Llama developers review the relevant license requirements, your use case, and deployment scale to help you use Llama appropriately in commercial environments.
How much GPU do I need to run Llama 3.1 70B?
GPU requirements depend on the model precision, quantization, context length, and expected traffic. A 70B model generally requires substantial GPU memory, but techniques such as 4-bit quantization with AWQ, GPTQ, or GGUF can significantly reduce memory requirements. Our engineers size the infrastructure around your actual latency and throughput needs rather than overprovisioning GPUs.
Should I fine-tune Llama or just use RAG?
Choose RAG when your application needs access to frequently changing or proprietary knowledge. Fine-tuning is more suitable when you need to change model behavior, response style, task performance, or domain-specific capabilities. In many enterprise applications, our Llama developers combine RAG with targeted fine-tuning for stronger results.
What's the difference between Llama 3.1 and 3.2 for my use case?
Llama 3.1 is suited to demanding language workloads and long-context applications, while Llama 3.2 introduces smaller models for lightweight and edge use cases alongside vision-capable variants. When you hire a Llama 3 developer, we evaluate your accuracy, context, latency, hardware, and cost requirements to select the appropriate model.
Can you deploy Llama fully on-prem with no external calls?
Yes. Our Llama developers for hire can deploy Llama entirely within your on-premises infrastructure or private cloud. We can configure self-hosted inference, RAG, APIs, monitoring, and GPU infrastructure without requiring third-party inference calls, helping organizations maintain greater control over sensitive data.
How much does it cost to hire a Llama developer?
The cost depends on the developer's expertise, engagement duration, project complexity, and whether you need capabilities such as fine-tuning, RAG, inference optimization, or infrastructure deployment. CodesClue offers flexible engagement options, including hourly, monthly, and fixed-scope models, so you can choose an approach aligned with your requirements.
Can you fine-tune Llama on our proprietary or industry-specific data?
Yes. Our Llama model fine-tuning services can adapt Llama models to proprietary datasets and specialized business requirements. We use approaches such as LoRA, QLoRA, PEFT, and supervised fine-tuning, depending on the model, dataset, compute budget, and desired outcome.
Can your Llama developers optimize models for lower GPU and inference costs?
Yes. Our engineers optimize the complete inference stack, including model selection, quantization, GPU sizing, batching, and serving frameworks such as vLLM and TGI. The goal is to achieve the required throughput and latency while avoiding unnecessary GPU capacity and reducing ongoing inference costs.
Where is your team based?
Our team is based in India, the United States and Germany, which gives you working-hours overlap across Asia, Europe and North America.
How do you price projects?
Three ways, matching our engagement models: a dedicated team billed monthly, staff augmentation where you add individual engineers to your own team, or a fixed-scope project with an agreed timeline and budget. The first consultation is free; we scope your requirements there and send a written estimate within 24 hours.
How do you handle security and compliance?
Security is built into every engagement: data encrypted in transit and at rest, role-based access control, logging and monitoring, and audit-ready configuration. For regulated industries we design to the relevant standard, for example HIPAA-ready systems for healthcare. We sign an NDA before any engagement, so your systems and data stay confidential from the first conversation.
Ready to hire LLaMA developers?
Tell us what you need. We shortlist developers for you to interview, and there is no charge for project management.